# Fusical: Multimodal Fusion for Video Sentiment
## Introduction
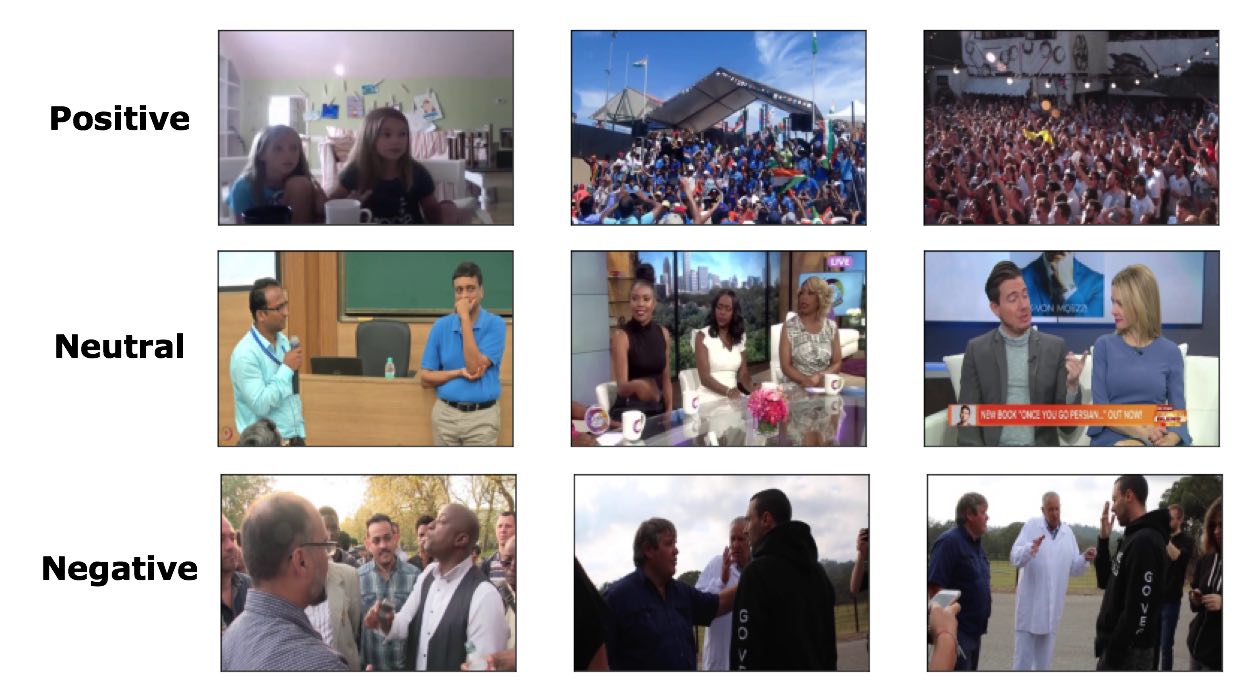
Despite cultural diversity, emotions are universal. We will undertake the [EmotiW 2020 challenge](https://sites.google.com/view/emotiw2020), doing group-level sentiment recognition on videos from across the globe. Given short clips, the goal is to predict whether the video sentiment is positive, neutral, or negative. This problem is interesting because audio-visual sentiment analysis has implications in psychology and mental health.
Our paper was accepted at the [22nd ACM International Conference on Multimodal Interaction](http://icmi.acm.org/2020/): https://dl.acm.org/doi/10.1145/3382507.3417966
## Dataset
We worked with the EmotiW 2020 dataset.
### Architecture
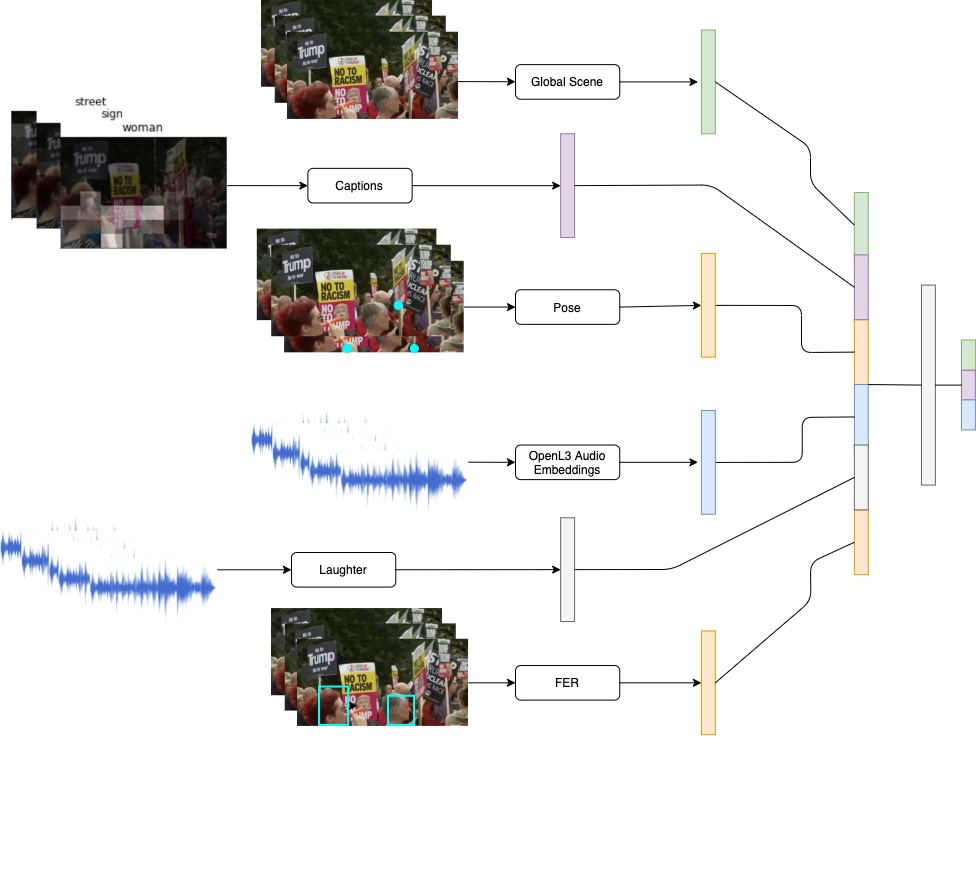
We ensembled models from four modalities: overall scene, pose, audio, and facial.
## Getting Started
To start, please check out our [presentation](https://drive.google.com/file/d/1YVe4pVK5DY4MlS26WsfrO9UCYuBrR_X1/view) and [slide deck](https://docs.google.com/presentation/d/1o5u3VHBYzWLeiQOaD43SvhYKbgfHvc6kYxQ322Xsl4o/edit).
### Code Layout
The code is organized as follows:
- src/ - preprocessing, generation, and classification code
- notebooks/ - notebooks for training and prediction
### Try it out
Run this [notebook](notebooks/ensemble/ensemble_fc_predictions_v2-with-laugh.ipynb) to see how our model works on the dataset.
### Model Emporium
We provide many of the models we trained [here](model-emporium.md).
## Results
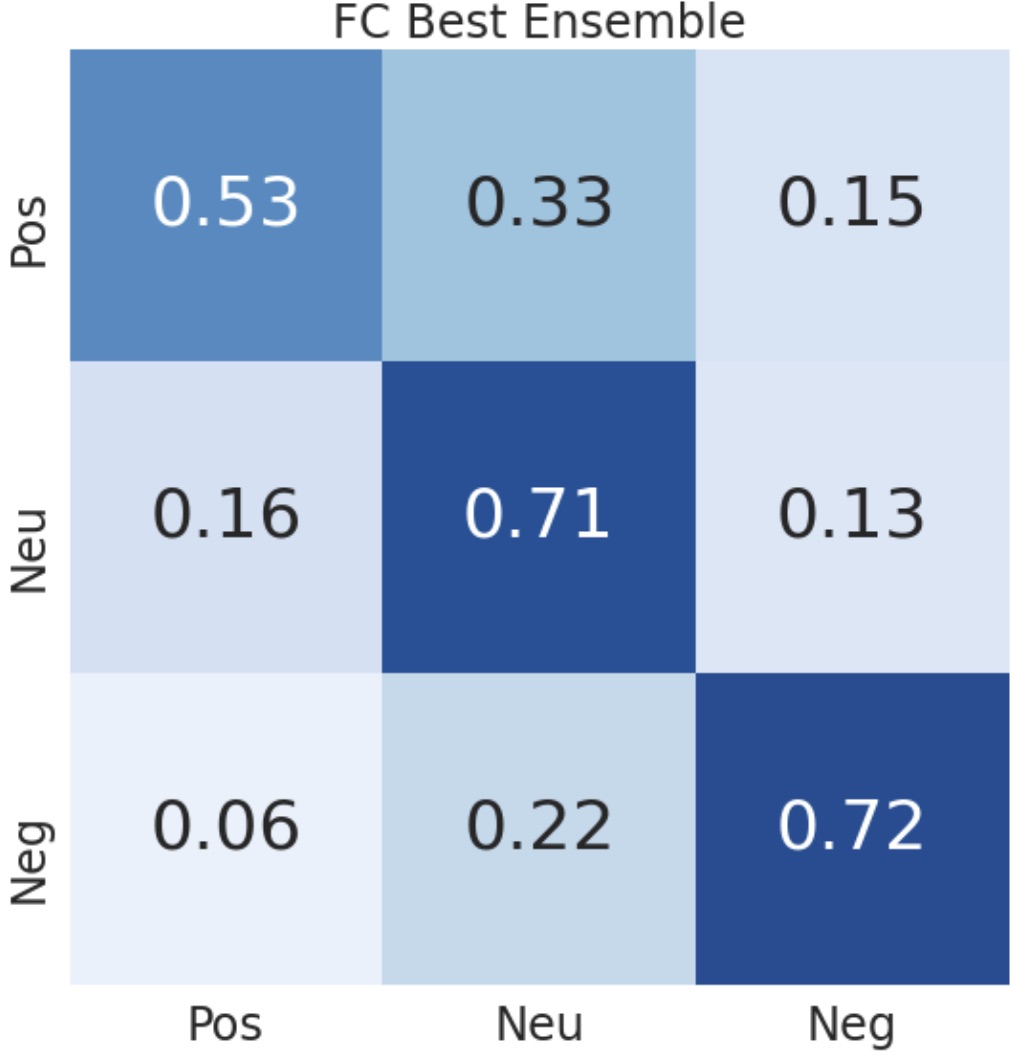
### Final Ensemble
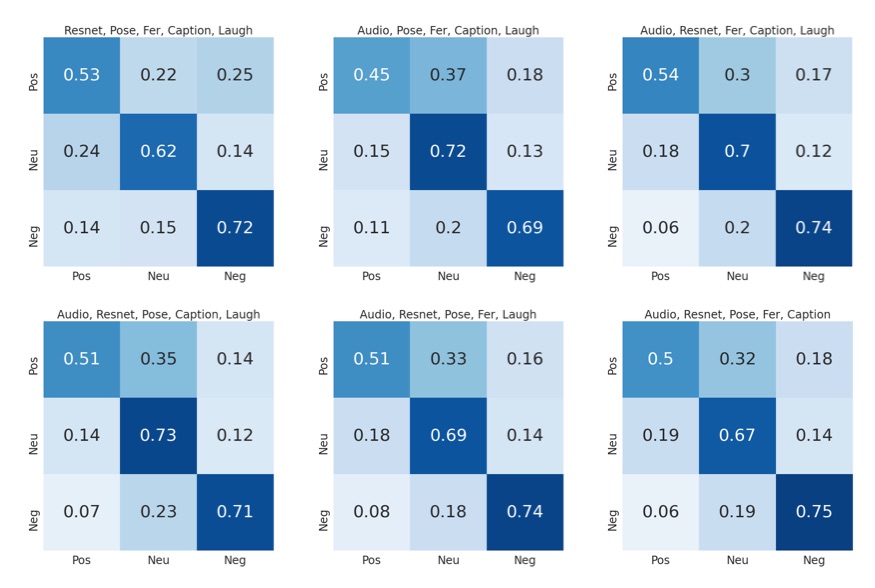
### Ablation Study
### Table - Individual Modalities
Results as reported based on the EmotiW 2020 validation dataset.
| Modality | Accuracy | F1-Score
| ------------- | ------------- | ------------- |
| Scene | 0.546 | 0.541 |
| Pose | 0.486 | 0.489 |
| Audio|0.577|0.577|
| Face | 0.4 |0.348 |
| Image Captioning | 0.505 | 0.506 |
### Table - Final Ensemble
| Dataset | Accuracy
| ------------- | -------------
| Validation | **0.640** |
| Test | **0.639** |
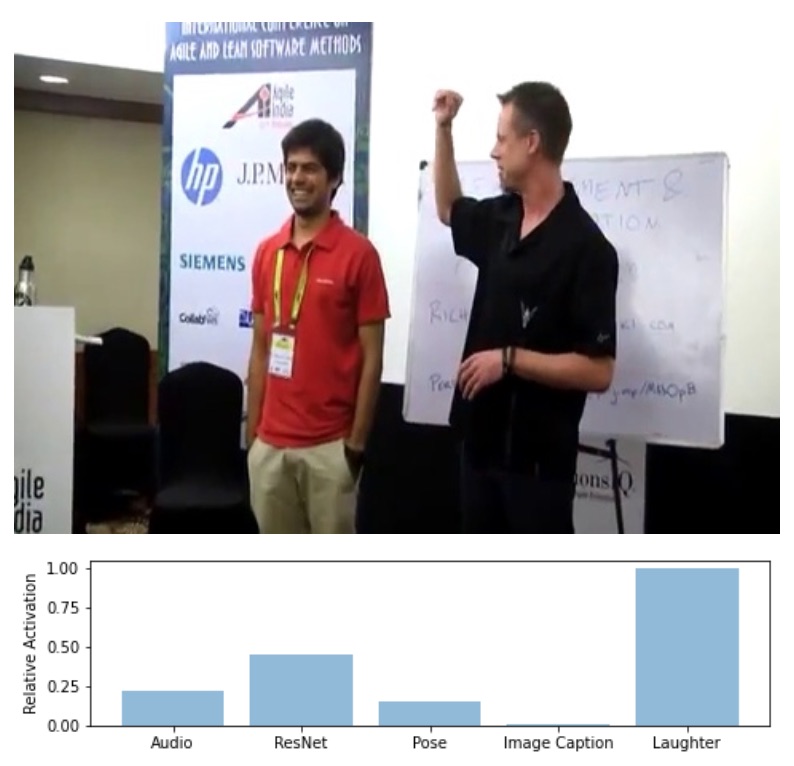
### "Saliency" Map
## The Team
[Boyang Tom Jin](https://www.linkedin.com/in/tomjinvancouver/), [Leila Abdelrahman](http://leilaabdel.com/), [Cong Kevin Chen](https://www.linkedin.com/in/cong-kevin-chen-11544186/), [Amil Khanzada](https://www.linkedin.com/in/amilkhanzada)
[CS231n - Stanford University](http://cs231n.stanford.edu/)
## Citing Our Work
```
@misc{2020fusical,
author = {Boyang Tom Jin and Leila Abdelrahman and Cong Kevin Chen and
Amil Khanzada},
title = {Fusical},
howpublished = {\url{https://github.com/kevincong95/cs231n-emotiw}},
year = {2020}
}
```